



The meta robots tag can only go in the <head> of an HTML page. For PDFs, images, video and other files you give the same directive with the X-Robots-Tag HTTP header. The header is part of the response the server returns with the file, so the setting is made in the server configuration, not in page content.
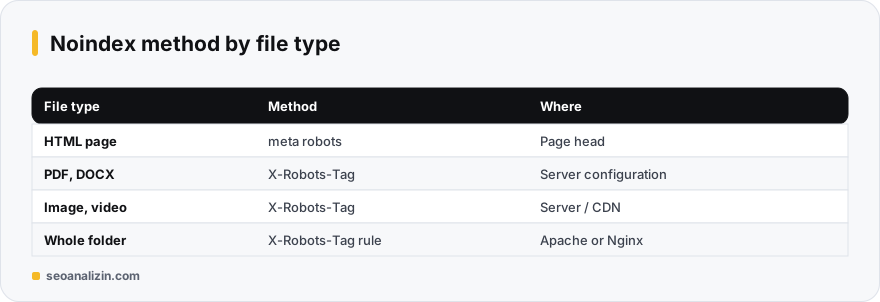
When to use it
- PDFs you do not want to appear in search (internal documents, old brochures).
- Image or media files you do not want in the index.
- When you need to apply noindex to hundreds of files with one rule (for example a certain folder or extension).
- Pages whose HTML you cannot touch.
Syntax
X-Robots-Tag: noindex
X-Robots-Tag: noindex, nofollow
X-Robots-Tag: googlebot: noindex
Apache example
<FilesMatch "[.](pdf|docx)$">
  Header set X-Robots-Tag "noindex, nofollow"
</FilesMatch>
Nginx example
location ~* [.](pdf|docx)$ {
  add_header X-Robots-Tag "noindex, nofollow";
}
After changing the configuration, reload the server and make sure there are no errors. Verify that the rule applies only to the target files; a wrong pattern can affect the whole site.
How to test
- See the response headers of the file address with the HTTP Header Checker; the
x-robots-tagline must be there. - On the command line,
curl -I https://example.com/file.pdfgives the same information. - The Search Console URL Inspection tool shows whether the file address is indexed.
Things to watch
- Googlebot must be able to crawl the file: the header of a file blocked by robots.txt cannot be read. See the noindex guide.
- The header rule can disappear in a CDN or cache layer; test the response that reaches the end user.
- Removal from the index takes time and needs a recrawl.
Example: removing old PDFs from search
Your site has 80 old PDF brochures in the /files/ folder and they outrank newer content in search results. Writing a single rule for the folder is far more practical than dealing with 80 files: apply the Apache or Nginx rule above to this folder only, then test a few PDF addresses with a header checker.
Removal from the index is not immediate. Wait until Google recrawls the files, and during this time do not block the PDFs with robots.txt; if you do, the header cannot be read.
Short answers on X-Robots-Tag
What is the difference between X-Robots-Tag and meta robots?
The function is the same. The difference is where it is applied: one is inside the HTML, the other in the HTTP response.
If they conflict, which applies?
Google applies the most restrictive rule. Still, avoid creating a conflict.
How do I keep images out of Google Images?
Apply X-Robots-Tag: noindex to the image files, or block Googlebot-Image with robots.txt.



Join the discussion
Share your experience or ask a question about this guide.